This is the third post in my recurring series about using AI tools for software development. The first covered early 2023 through the end of 2025. The second covered Q1 2026, when Claude Code became my main development environment and I was mostly figuring out how to manage multiple agent sessions without losing track of everything.
Q2 was different. I didn’t adopt one big new tool that changed everything. Instead, the quarter was about which habits survived after the novelty wore off, which tools became default, and which parts of agentic development started to feel like the real bottlenecks.
The short version is that Codex became my default tool, Claude Code stayed important for heavier work, and context management became the thing I think about constantly.
April — Building Personal Workflows on Top of Agents
At the start of the quarter I was still deep in Claude Code. The most useful experiment wasn’t a coding task exactly, but a custom research workflow.
I built a research-junshi skill and a
research-checkin workflow for keeping research projects
moving. The idea was to sync the active state of a research project,
then use that state to produce a daily digest of related papers, ideas,
and possible next steps from arXiv and top software engineering
venues.
This is one of the places where AI tools feel genuinely different from normal automation. A script can fetch papers. A feed reader can show me what’s new. The useful part was having a workflow that knew what I was currently thinking about and could keep nudging the project forward from that context.
For research, that mattered. When I was actively focused on a paper, the workflow helped me keep momentum. It gave me small hooks back into the problem every day: related work to skim, nearby ideas to consider, possible framing changes. It felt like a lightweight research assistant tuned to my current project instead of a generic paper recommender.
It didn’t become a universal daily habit, though. Once June shifted more toward engineering work, I stopped using it as much. That has been a recurring pattern for me: workflows that are extremely useful in one mode of work don’t automatically survive when the mode changes. The tool was good, but its value depended on being in a research-heavy period.
The Context Problem Got Louder
The biggest practical problem this quarter wasn’t model intelligence. It was context.
I was running many sessions across different projects, and the hard part wasn’t always getting an agent to do a task. The hard part was remembering what I’d asked, what had already been tried, what was blocked, and what state each project was in.
That led to another set of custom workflow experiments: daily and weekly summary skills. The daily summary scans Claude Code session transcripts for a given day and turns them into a structured recap: projects touched, accomplishments, trouble spots, follow-up work, and anything that needs attention. The weekly summary rolls those daily summaries up into a multi-day view organized by day and project.
This solved a real problem. When I’m running multiple agents, the work becomes strangely hard to account for. A lot happens, but it’s distributed across terminal sessions, compacted conversations, temporary branches, and half-finished ideas. At the end of the day I can have the feeling that I was busy, but not a clean memory of what actually moved.
The summaries help because they give me a recoverable thread. They aren’t perfect, but they reduce the “what was I even working on?” feeling. More importantly, they make agent work feel less ephemeral. Instead of every session disappearing into terminal scrollback, there’s a durable record of the day.
This is also where I started to feel the difference between using agents occasionally and using them as the center of the workflow. Occasional use creates local productivity. Daily use creates coordination problems. I need memory, summaries, handoffs, project state, and ways to decide what deserves attention next.
May — Codex Became the Default
The biggest tool shift happened around May. I started using Codex more and more, partly because I kept hitting Claude Code limits and partly because Claude Code had enough availability issues that it stopped feeling like the always-on default.
This was a reversal from Q1, when I was still frustrated with Codex. I’d try it when Claude Code ran out, get annoyed, and go back as soon as I could. But by the middle of Q2 the tradeoff had changed. Codex was quicker, more available, and good enough for a large amount of day-to-day work.
That doesn’t mean Claude Code went away. It still feels better for heavier tasks, especially when I already have well-developed skills or workflows built around it. If I need something that benefits from a lot of project-specific scaffolding, Claude Code still fits naturally.
But for smaller work, Codex became easier to reach for. Quick fixes, repo inspection, drafting changes, implementation tasks where I already know the shape of the solution: Codex became the tool I used without thinking much about it.
By the end of June, the split was pretty clear:
- Codex for light and medium engineering work where speed and availability matter.
- Claude Code for heavier work, research workflows, or tasks where my existing Claude-specific skills matter.
- ChatGPT or Claude chat for quick questions, writing help, and thinking through ideas outside the repo.
That split hasn’t stabilized into a grand theory. It’s just the pattern I actually follow.
Writing, Reasoning, and Tool Fit
One thing that became clearer this quarter is that I don’t think about AI tools as a single category anymore. They have different fits.
For coding, the terminal is where the work happens. I want the model inside the repo, with access to files, tests, git state, and commands. The chat window isn’t enough for serious implementation work.
For writing, I still care a lot about voice. Claude often feels better for long-form writing and revision. It tends to produce prose that is closer to how I want to sound, while other tools can drift into bullets, summaries, or generic structure too quickly.
For quick questions, I’m less picky. The best tool is usually whichever one is open and fast.
This matches the broader pattern I keep seeing other people describe: coding is the center of the workflow, but the workflow is layered. There is no single thing called “using AI.” I use different models and surfaces for different kinds of work. Terminal agents for code. Chat for thinking. Specialized workflows for research. Maybe IDE tools for narrower completion or editing tasks.
The important part isn’t picking one winner. It’s knowing which surface matches the job.
The AI Vampire Is Still Real
I also kept running into what Steve Yegge calls the “AI Vampire”: the feeling that AI tools make it too easy to keep delegating one more thing.
The feedback loop is what makes this different from ordinary workaholism. If I have an idea at 9:30 p.m., I can hand it to an agent and see progress immediately. If that works, I can hand it another task. Then another. The cost of starting work drops so low that stopping becomes the harder action.
I don’t have a good solution for this yet. I’m aware of it, and I can tell when it’s happening, but awareness doesn’t automatically create a boundary. The tools are useful enough that the unhealthy pattern isn’t obvious in the moment. It feels productive because it’s productive.
That’s the uncomfortable part. The problem isn’t that the work is fake. The problem is that real progress becomes available at any time, with almost no activation energy.
Comprehension Debt
Another shift this quarter was my relationship with agent-written code.
In late 2025, I was still trying hard to understand every line. If an agent wrote a feature, I wanted to read through the implementation carefully and make sure I knew what happened.
That has changed. I still review important changes, and I still manually test things when needed, but I don’t read every line with the same intensity. I’ve become more comfortable trusting agents for routine implementation work.
This is useful, but it creates comprehension debt. The codebase moves faster than my mental model. I may know what task was completed, but not exactly how the solution was structured. After enough of that, the risk isn’t that the code fails immediately. The risk is that I become less able to steer the system because I no longer understand the details I’m asking agents to modify.
The compensation strategy I’ve been using is to spend more time upfront. Before implementation, I often ask the agent to investigate the codebase and write a plan. I review the plan, the intended files, the expected shape of the change, and the assumptions. Then the agent implements.
The two panels below show the same pipeline, task to merged code, with the human review gate in amber. In late 2025 it sat after the implementation. Now it sits after the plan, and the purple bars are the comprehension debt that builds up downstream of it.
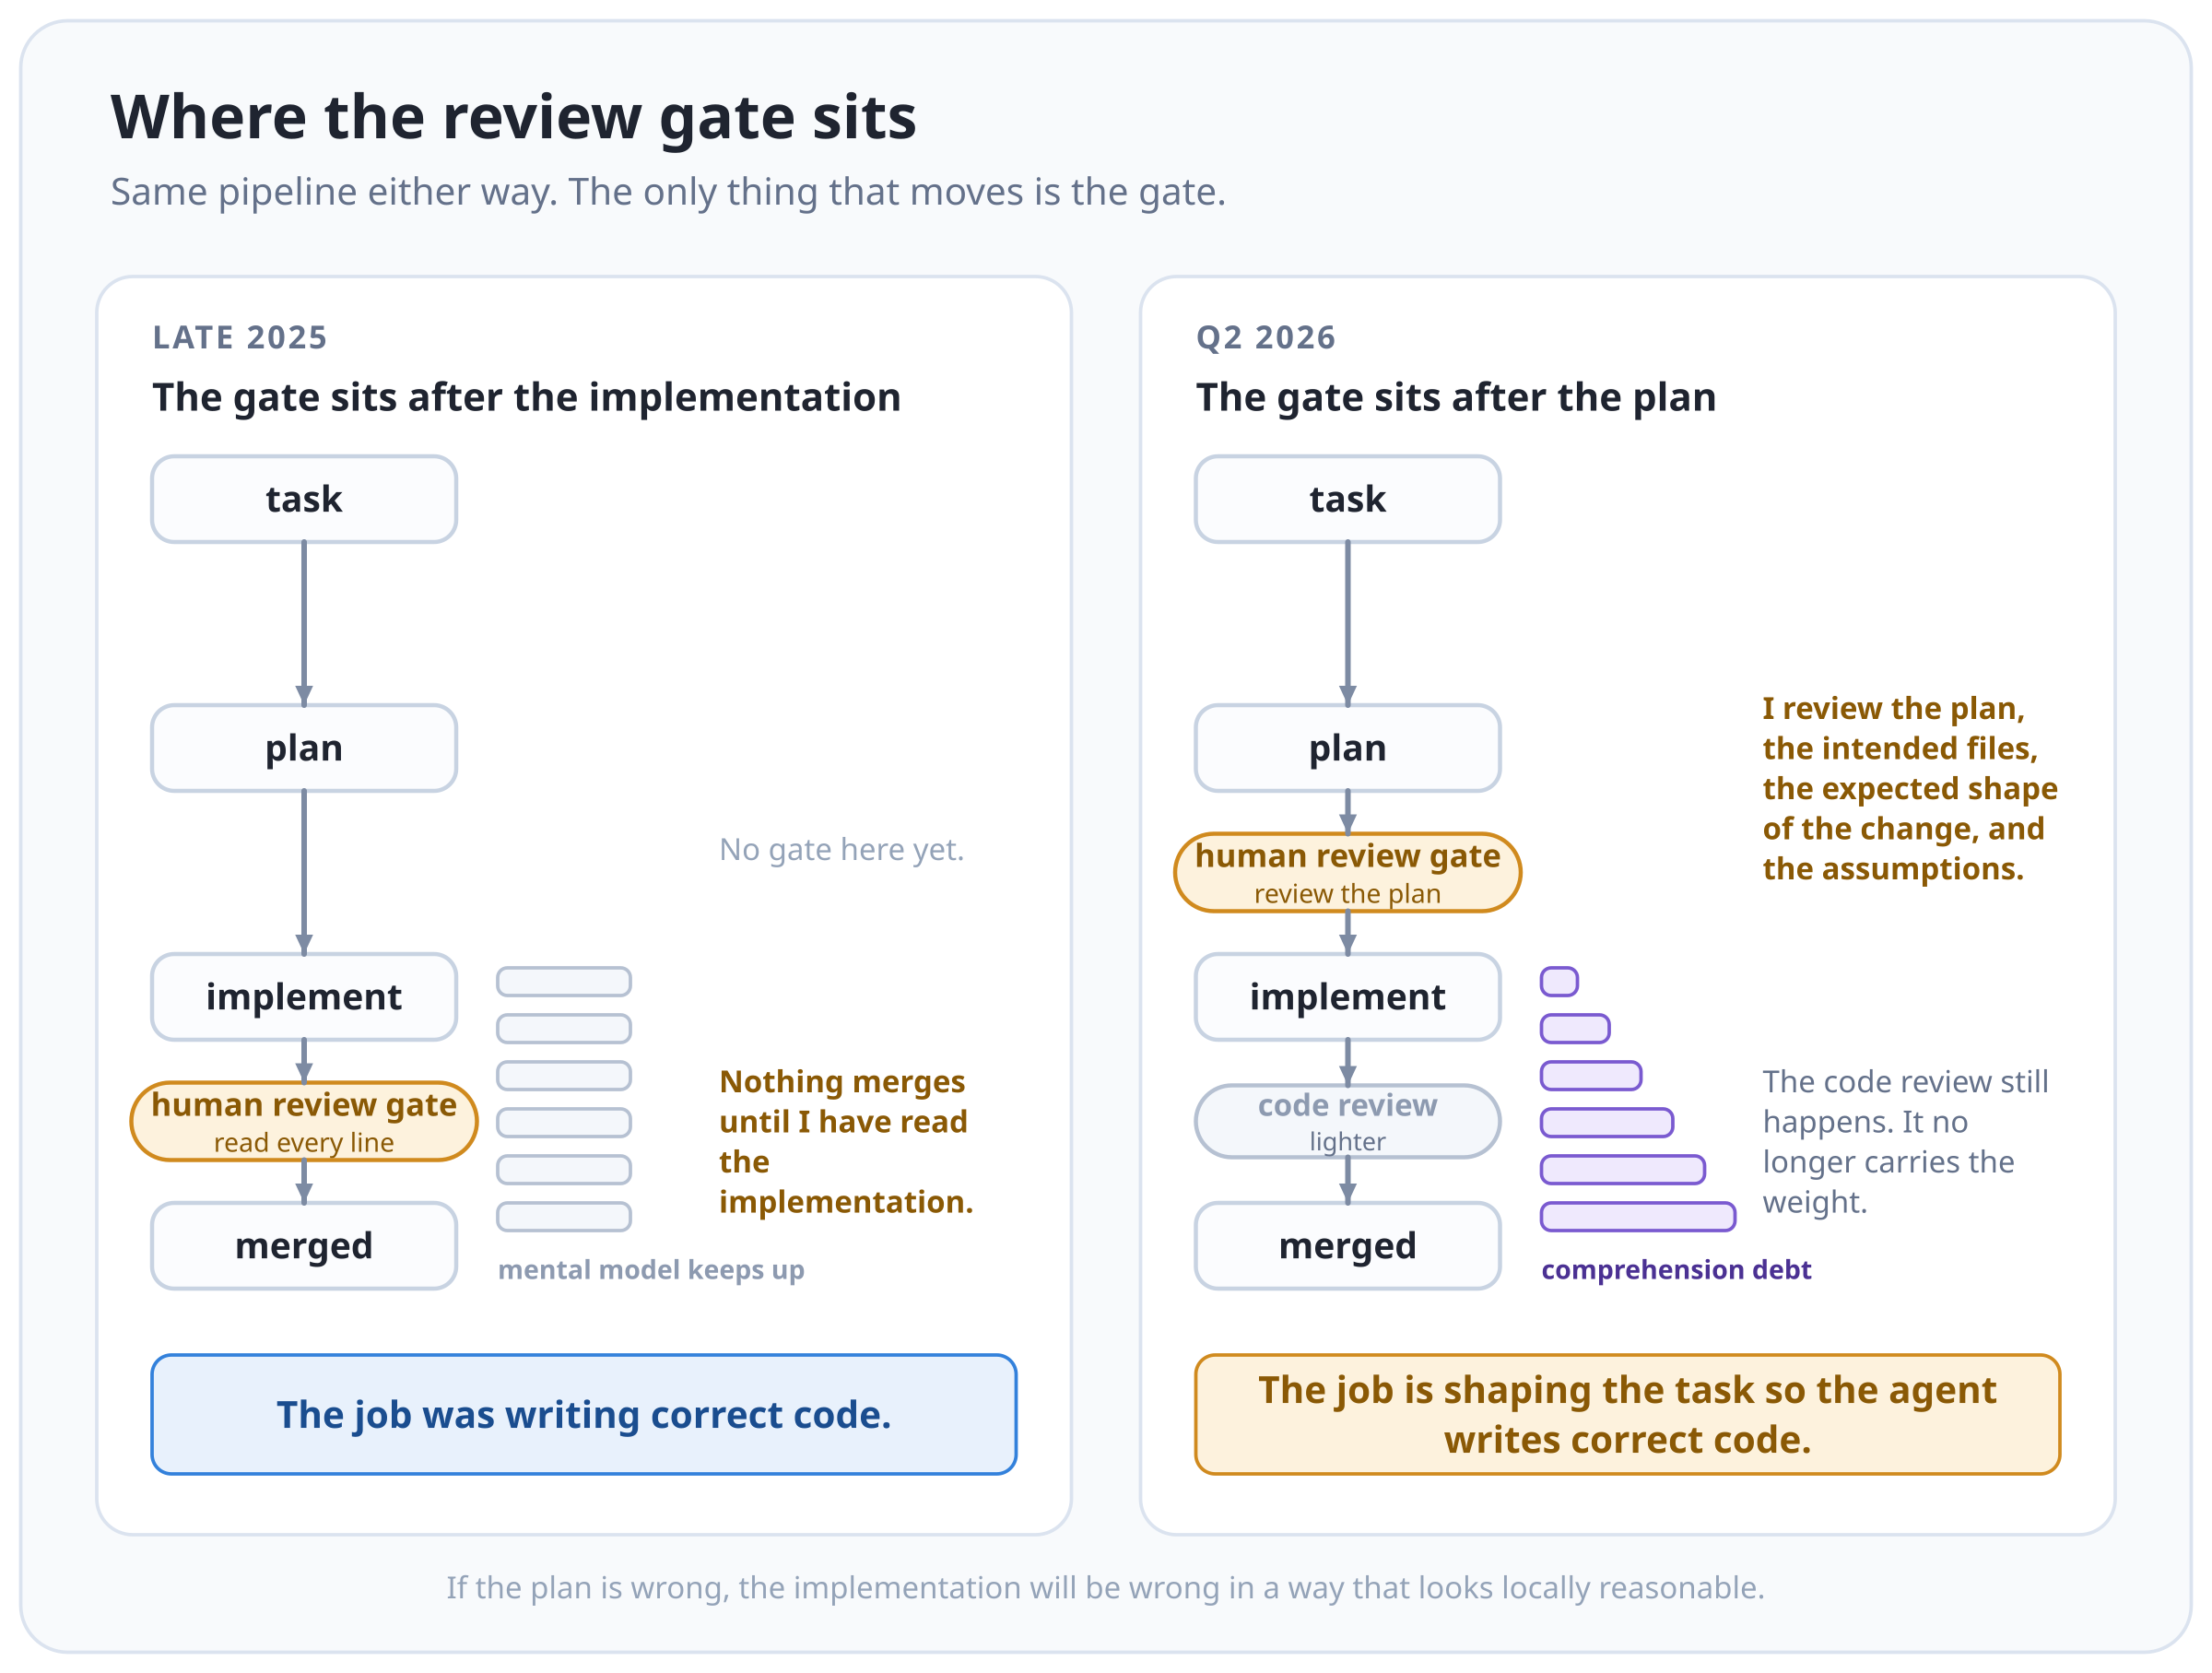
Little else changes. The stages are the same and they run in the same order. Moving one checkpoint earlier is the entire adjustment, and the debt is what it costs.
That means I’m shifting from verifying implementation to verifying intent.
I still need to inspect code, but the most useful review often happens before the code exists. If the plan is wrong, the implementation will be wrong in a way that looks locally reasonable. If the plan is right, I can trust more of the mechanical execution.
This feels like one of the biggest skill changes in agentic development. The job is less “write the correct code” and more “shape the task so the agent writes the correct code.”
June — The Workflow Is the Product
By the end of Q2, the most interesting work wasn’t any single generated feature. It was the workflow around the generated features.
The daily summaries, research check-ins, handoff documents, planning passes, and tool split all point in the same direction: the development environment is becoming a layer of personal process automation.
That sounds abstract, but in practice it’s very concrete. I need to know:
- What did I work on today?
- Which agent sessions are blocked?
- Which projects have dangling tasks?
- What context needs to survive compaction?
- What should an agent read before touching this code?
- When should I use Codex, Claude Code, or a chat model?
- Which work is real progress and which work is just momentum?
These aren’t coding questions in the old sense, but they now determine how effective the coding is.
The diagram below is that loop. The six stages run clockwise around the agent, and each workflow I built this quarter is pinned outside the ring at the stage it actually serves.
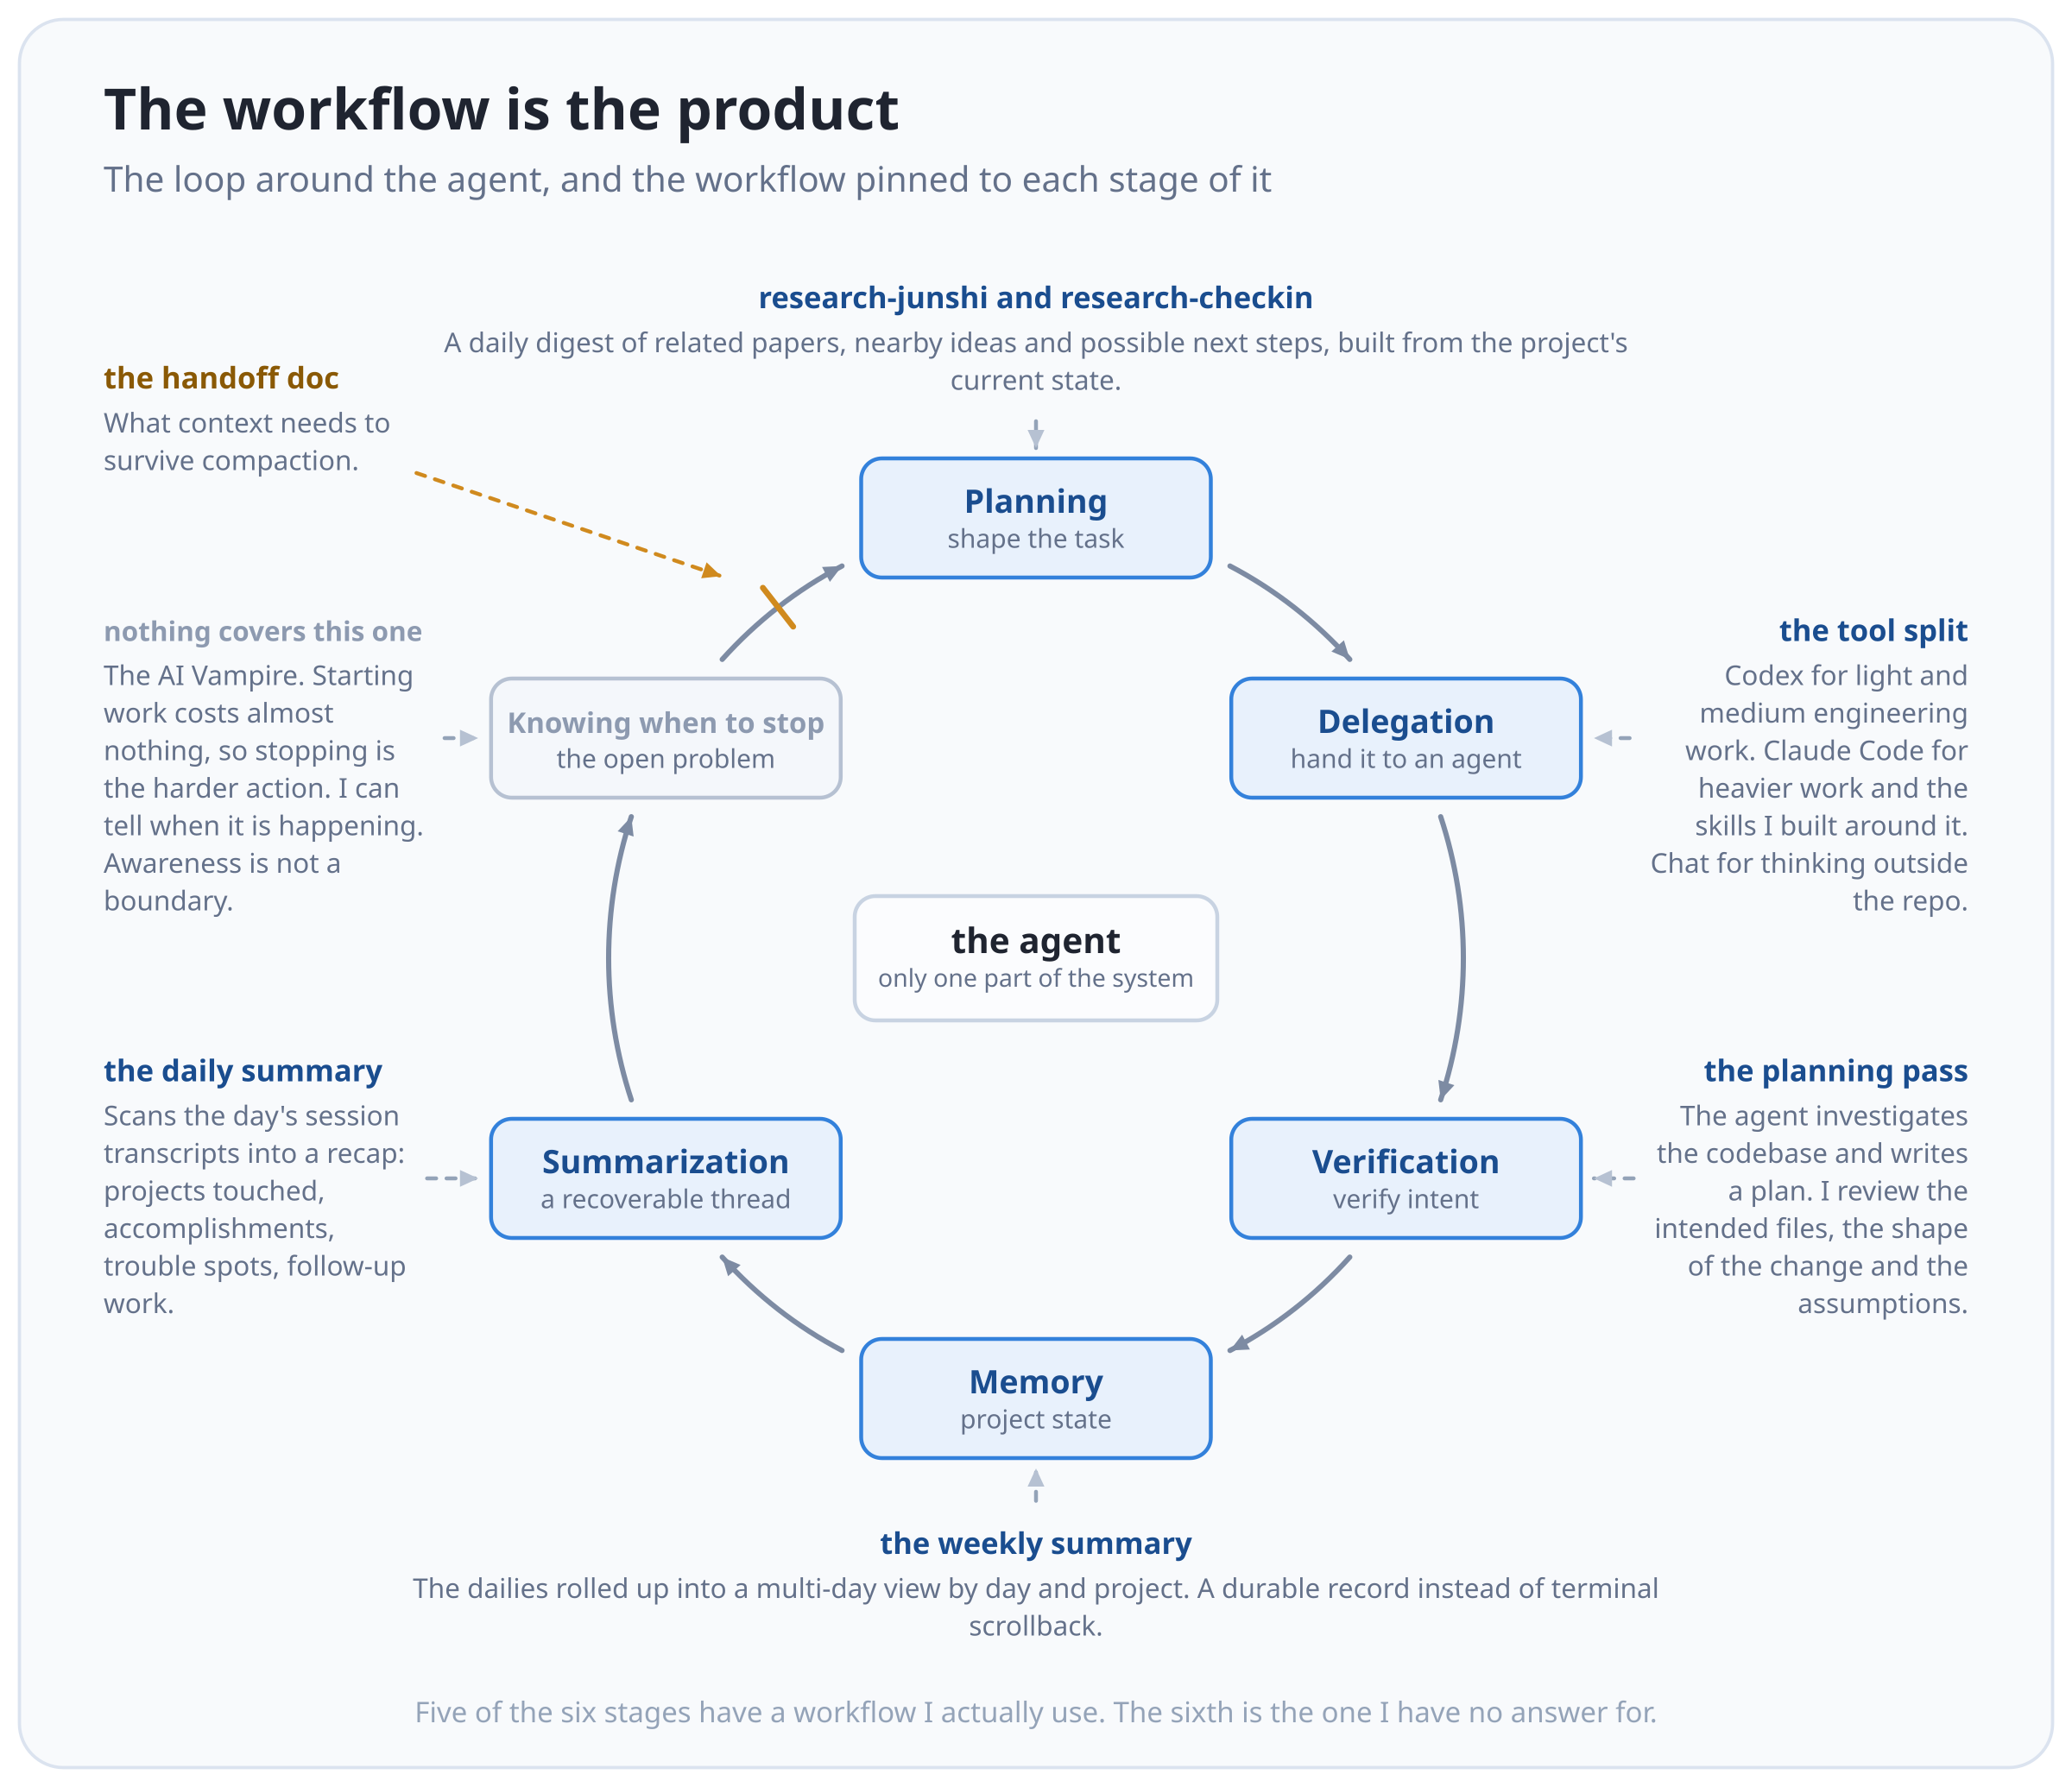
Five of the six stages have something I use. The sixth is knowing when to stop, and that one is still just me noticing.
Where Things Stand
At the end of Q2 2026, Codex is my day-to-day coding agent. Claude Code is still important, especially for heavier or more customized workflows, but it’s no longer the only place the work happens.
The biggest lesson of the quarter is that context management is the real bottleneck. Not in the narrow sense of “the model needs more tokens,” but in the broader sense of keeping project state, personal memory, task intent, and agent output aligned over time.
I’m still optimistic. The tools are better than they were three months ago, and I’m better at using them. But the work feels less like “learning to code with AI” now and more like building an operating system for my own attention.
Q1 was about going deeper with Claude Code. Q2 was about discovering that the agent is only one part of the system. The real system is the loop around it: planning, delegation, verification, memory, summarization, and knowing when to stop.